When should procurement consider liquid-cooled GPU servers?
Consider liquid cooling when GPU density, sustained load, rack limits, or power and thermal planning become central to the deployment.
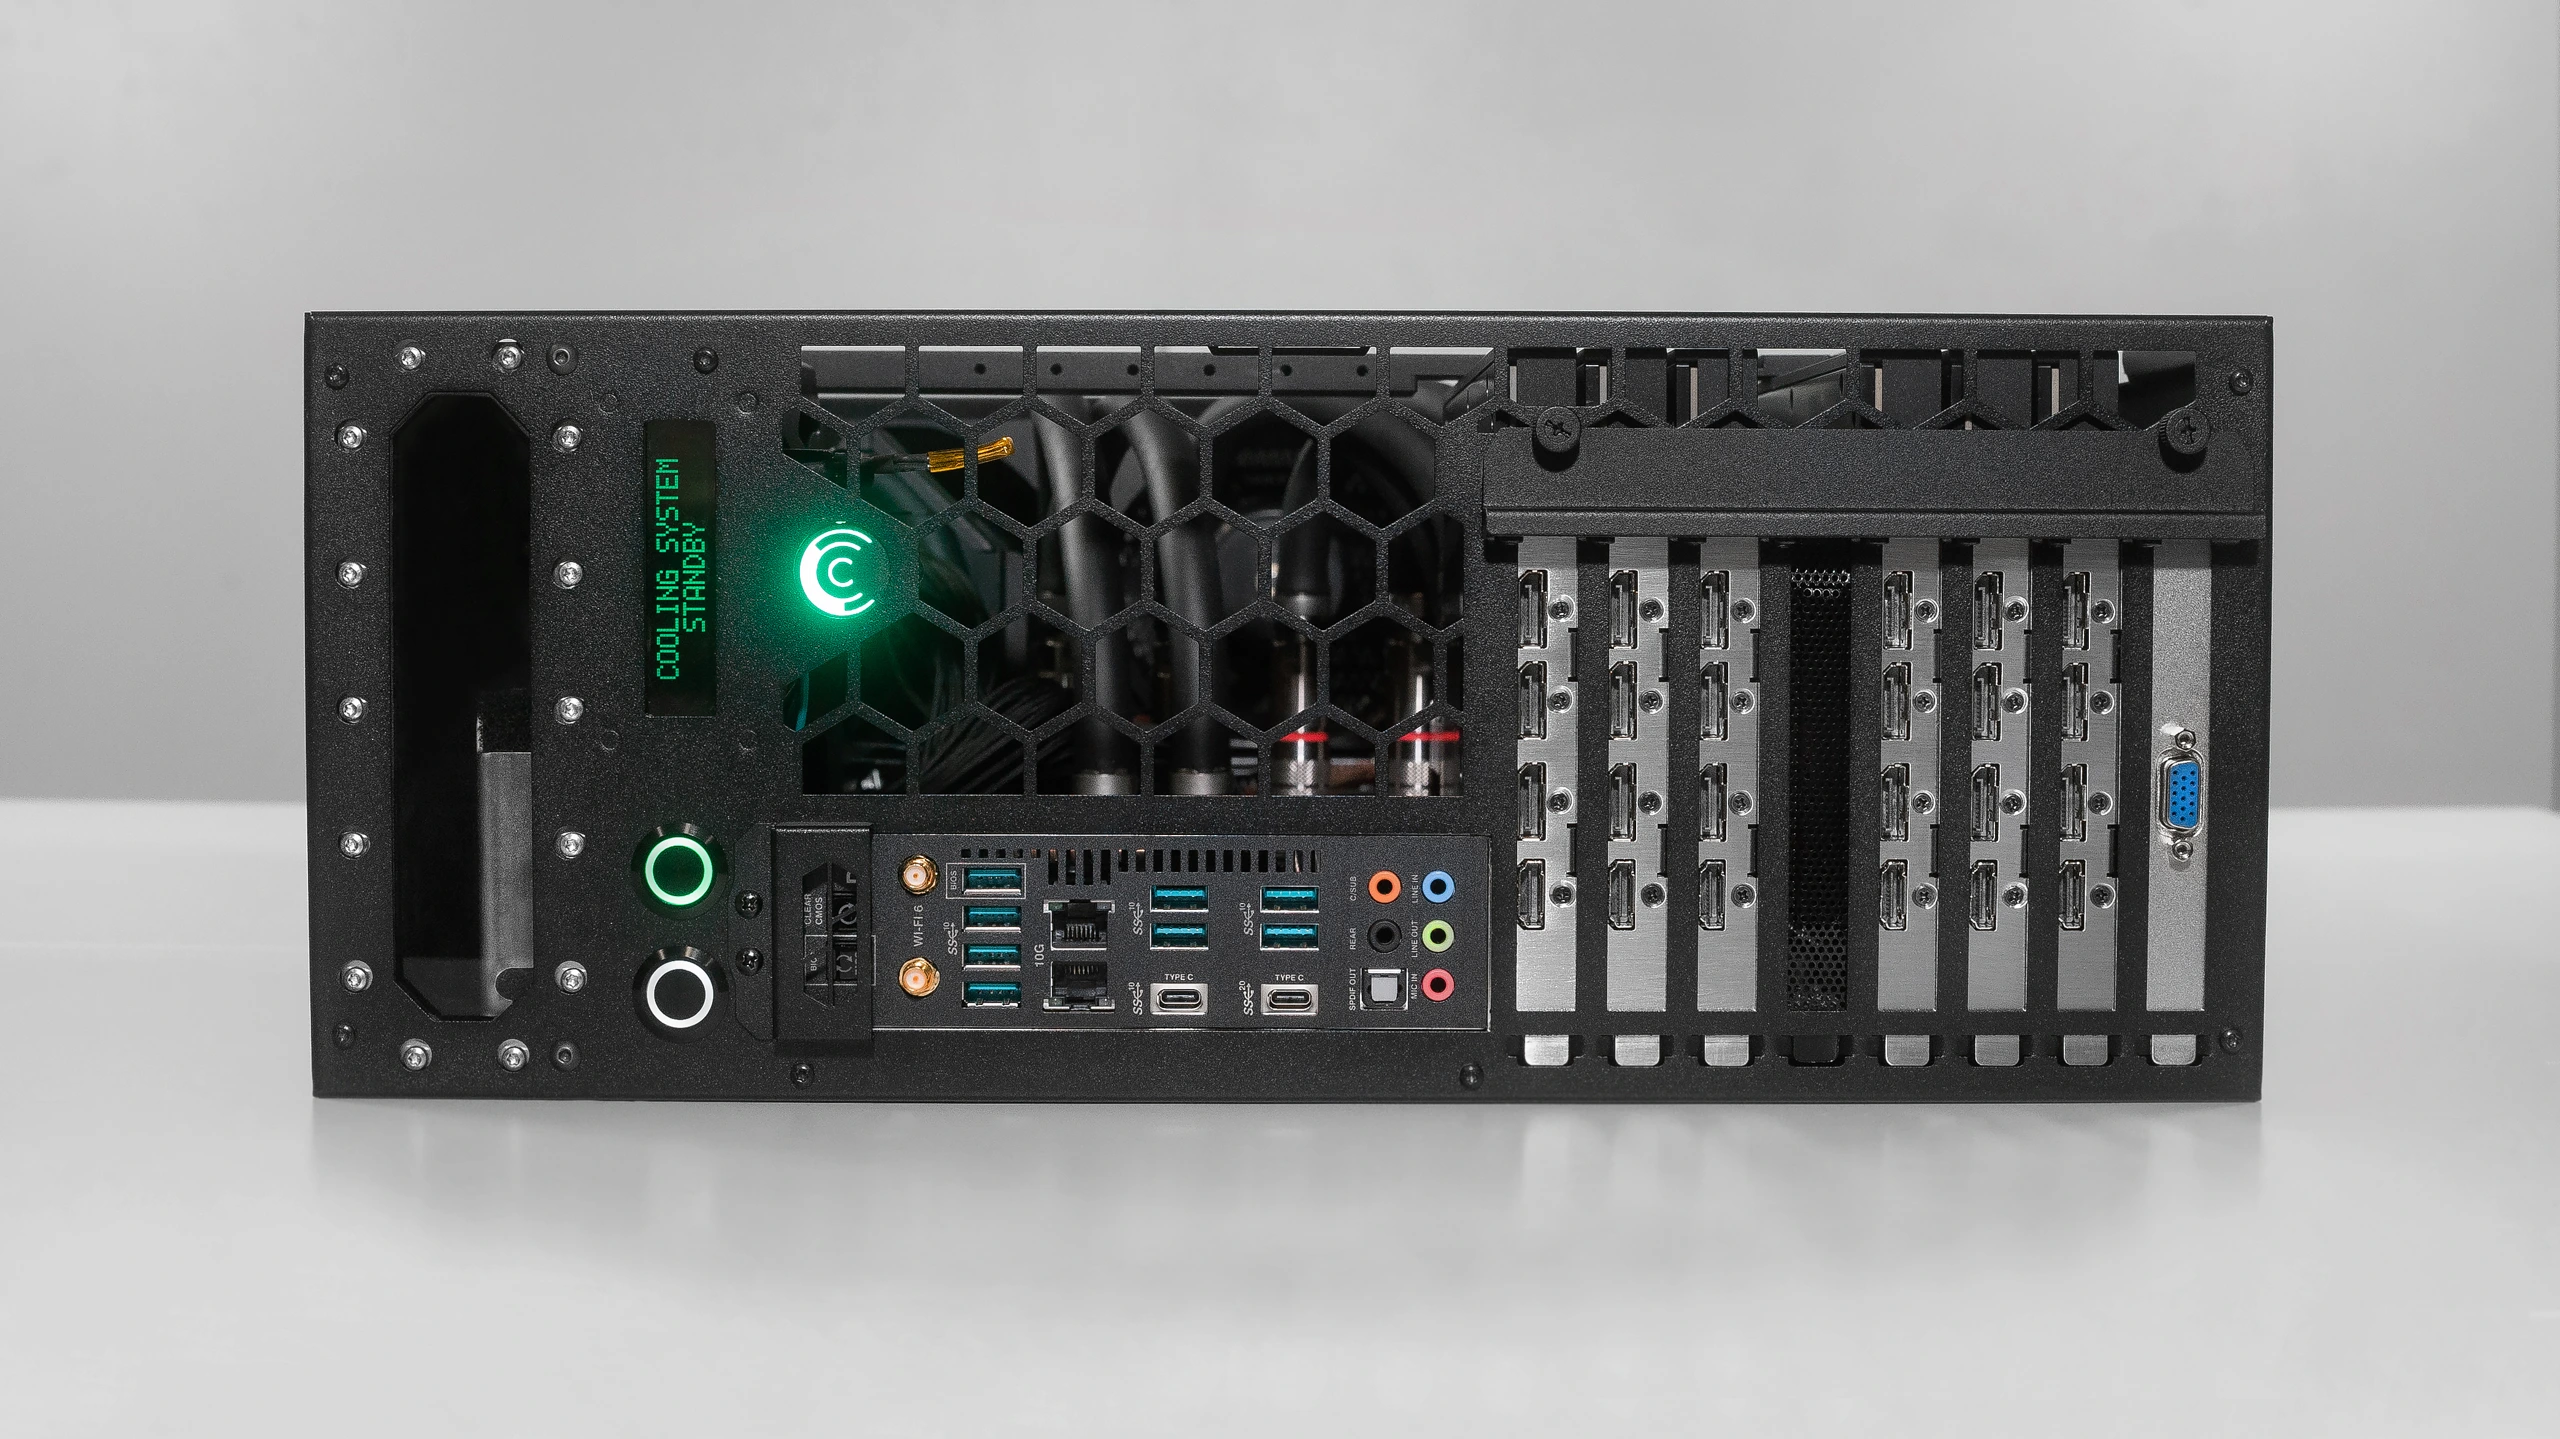
Evaluate liquid-cooled GPU systems with GPU count, heat load, rack constraints, power capacity, storage, networking, and service follow-up in one quote path.
Use the information here to pick a starting configuration, confirm the assumptions, and prepare a quote request.
For sustained AI, simulation, and HPC workloads where heat density matters.
Keeps cooling, power, rack, and component assumptions visible before quote review.
Helps buyers compare liquid-cooled systems with conventional server options.
Consider liquid cooling when GPU density, sustained load, rack limits, or power and thermal planning become central to the deployment.
The configurator keeps GPU count, CPU, memory, storage, power, and networking assumptions together, which makes the cooling and procurement review more precise.
Decision worksheet
Record these three decisions before opening the configurator or requesting a quote.
GPU density, power, rack, storage, network
For sustained AI, simulation, and HPC workloads where heat density matters.
Dense AI training, HPC, simulation, shared compute
Keeps cooling, power, rack, and component assumptions visible before quote review.
Open the rackable configurator and request a quote
Helps buyers compare liquid-cooled systems with conventional server options.
Continue to a related guide, or open the configurator once the assumptions are confirmed.
Plan an NVIDIA H200 server quote for AI training, HPC, or inference. EudTech confirms current availability, price, and delivery only after GPU count, CPU, memory, storage, power, cooling, and networking are defined.
Configure RTX PRO 6000 workstations for local AI inference, rendering, visualization, and simulation, then send the build to EudTech for Taiwan quote follow-up.
Choose between deskside AI workstations, rackable GPU systems, and integration-kit paths for Taiwan teams that need GPU acceleration, local inference, model development, rendering, or simulation workloads.
Explore GPU server cooling and liquid-cooled GPU server configurations for sustained AI and HPC workloads, then request a formal quote from EudTech.