Should inference buyers choose a workstation or a rack server?
It depends on concurrency, uptime, GPU density, rack availability, and management needs. The configurator keeps both options open for review.
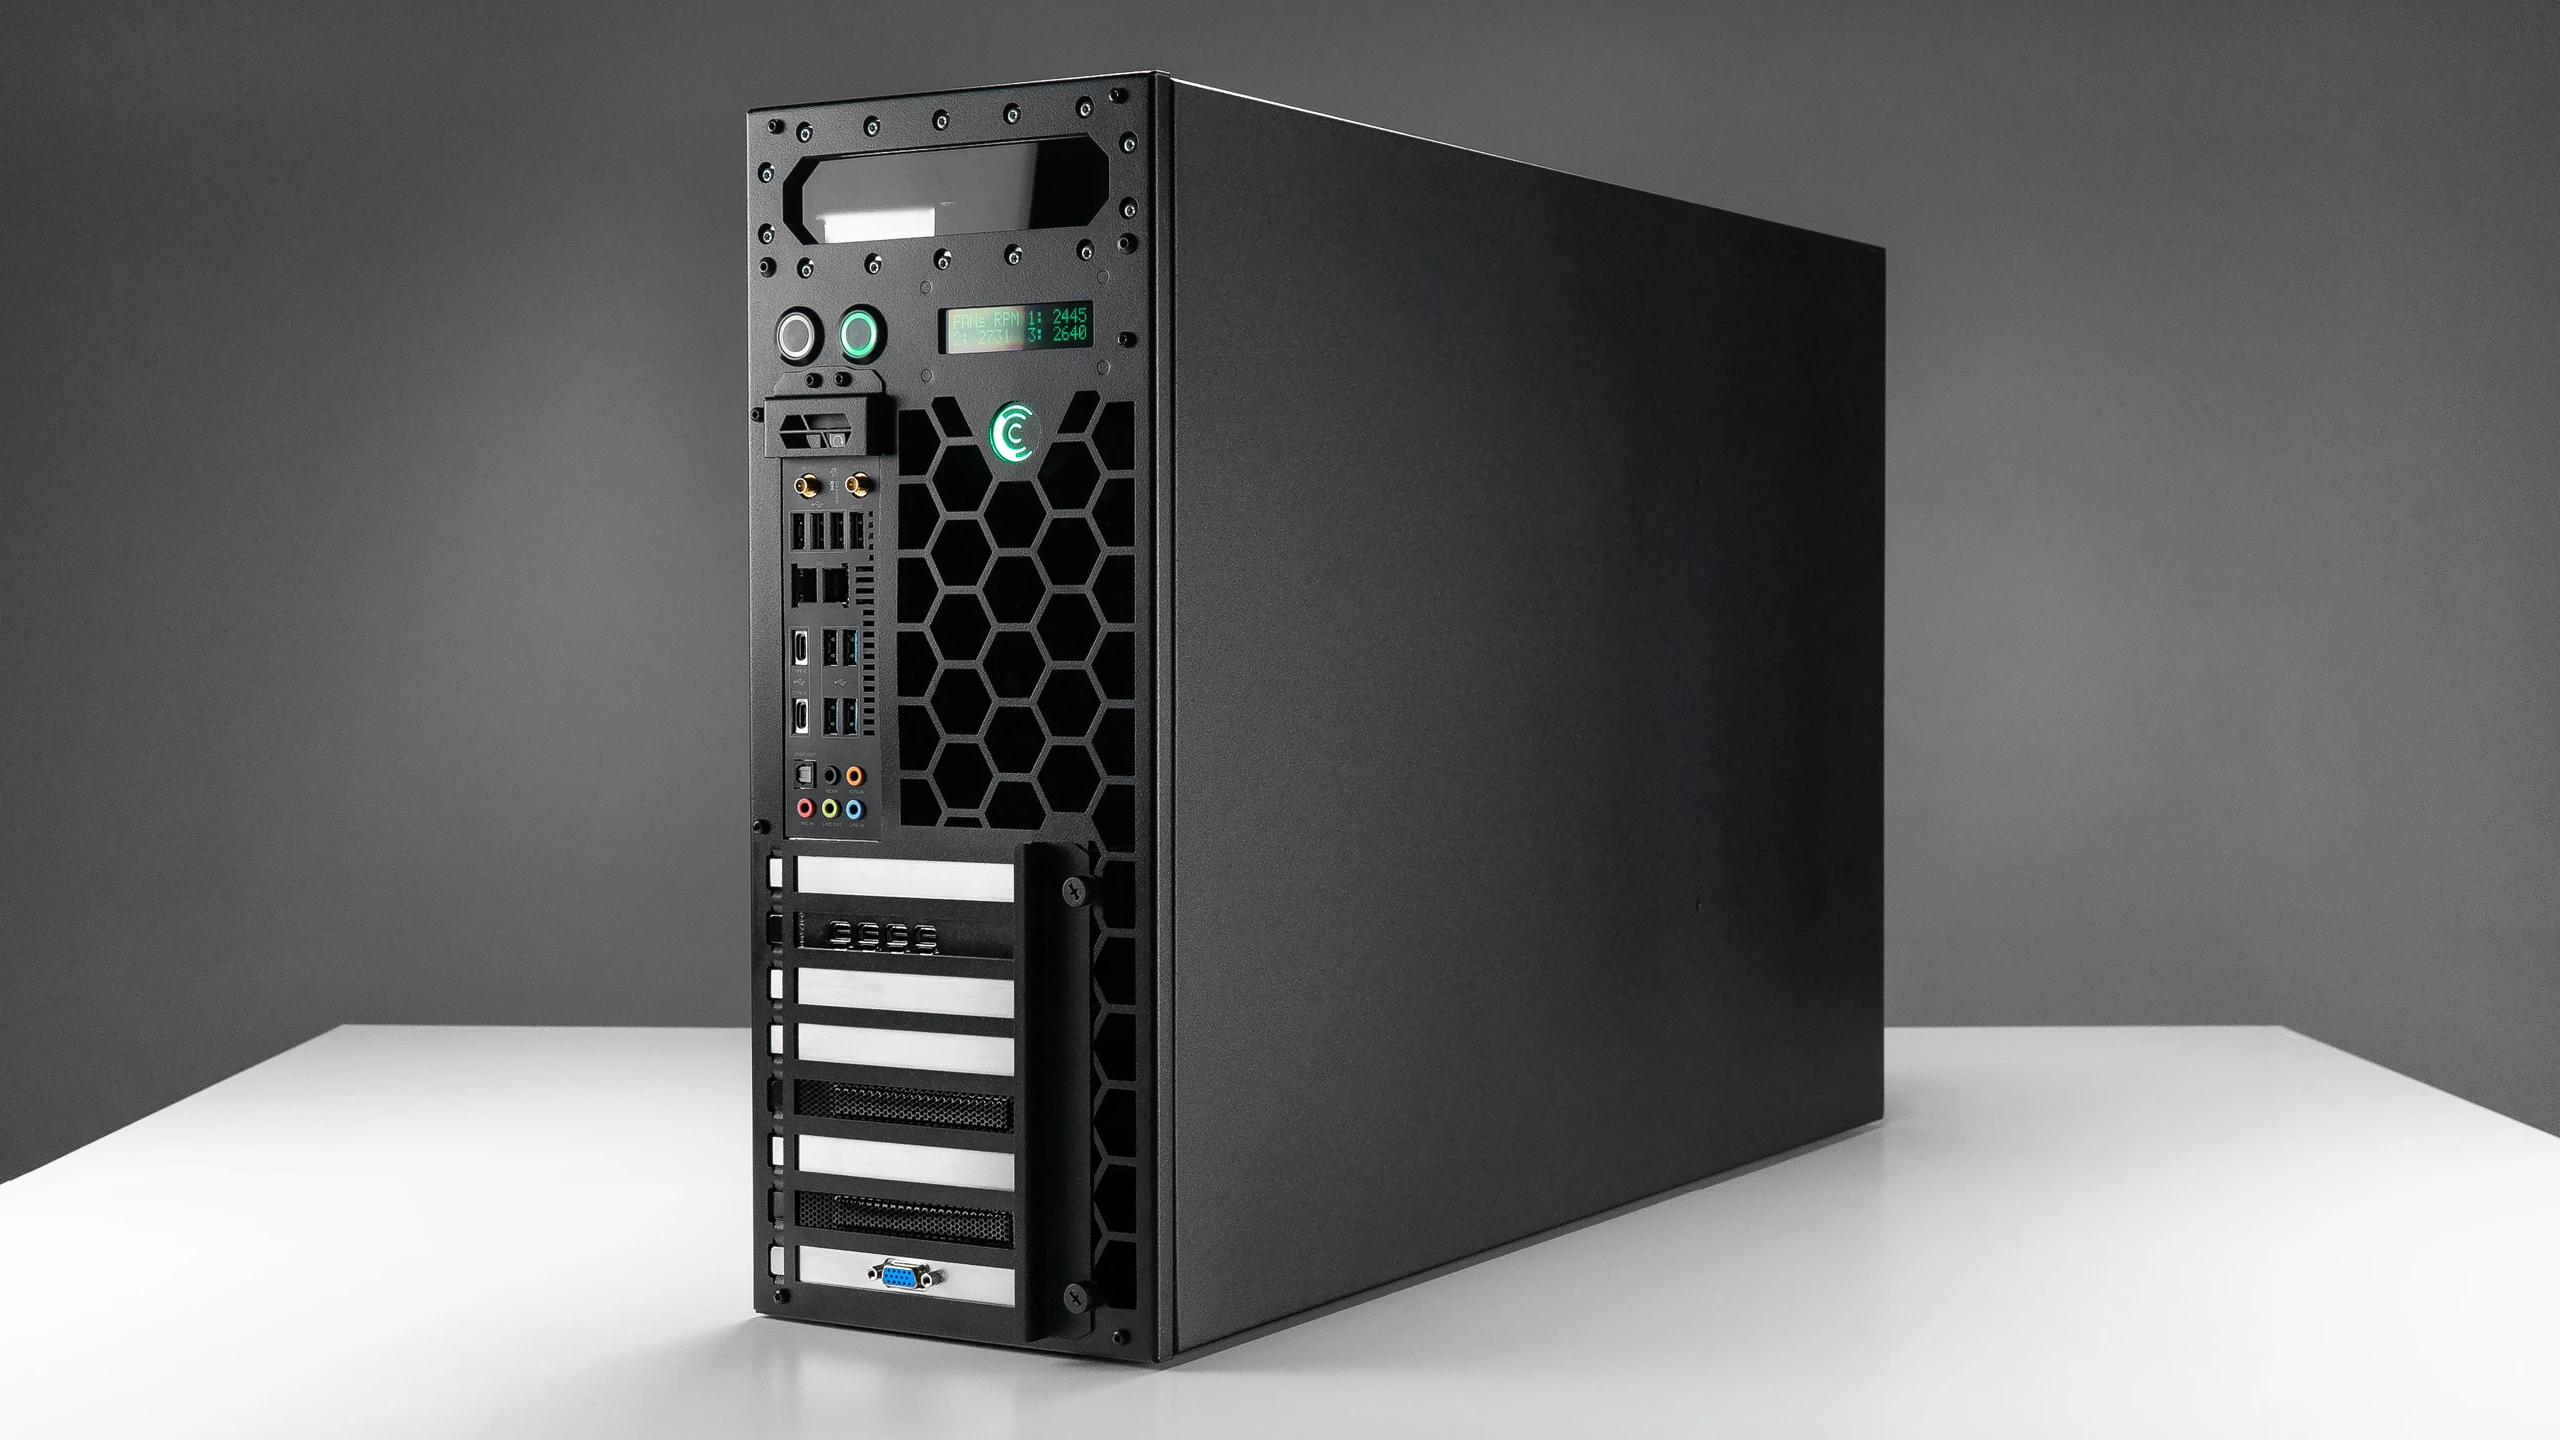
Start from a GPU server or workstation configuration. Record concurrency, model size, GPU memory, system RAM, NVMe storage, networking, and operations assumptions for the inference workload.
Clarify the workload and deployment constraints here, then decide the next step before requesting a quote.
For teams planning local inference, private model serving, and GPU-accelerated application deployment.
Configurator links help compare the workstation and rackable server directions.
The quote request keeps the hardware assumptions for technical and purchasing review.
It depends on concurrency, uptime, GPU density, rack availability, and management needs. The configurator keeps both options open for review.
Yes. Send the draft configuration with workload notes, and EudTech follows up on GPU memory, system RAM, storage, and networking.
Include model size, expected concurrency, response-time target, GPU memory, system RAM, NVMe storage, networking, and operating model. State whether the deployment is a workstation or a rack server. The configurator keeps the hardware choices for that review.
Decision worksheet
Record these three decisions before opening the configurator or requesting a quote.
Local AI inference and model serving
For teams planning local inference, private model serving, and GPU-accelerated application deployment.
GPU memory, system RAM, NVMe, network
Configurator links help compare the workstation and rackable server directions.
Taiwan quote follow-up
The quote request keeps the hardware assumptions for technical and purchasing review.
Continue to a related guide, or open the configurator once the assumptions are confirmed.
Plan an NVIDIA H200 server quote for AI training, HPC, or inference. EudTech confirms current availability, price, and delivery only after GPU count, CPU, memory, storage, power, cooling, and networking are defined.
Configure RTX PRO 6000 workstations for local AI inference, rendering, visualization, and simulation, then send the build to EudTech for Taiwan quote follow-up.
Choose between deskside AI workstations, rackable GPU systems, and integration-kit paths for Taiwan teams that need GPU acceleration, local inference, model development, rendering, or simulation workloads.
Explore GPU server cooling and liquid-cooled GPU server configurations for sustained AI and HPC workloads, then request a formal quote from EudTech.